CUA-SWE: When Computer-Use Agents Meet Visual Software Engineering
1Carnegie Mellon University 2University of Southern California 3University of Wisconsin–Madison 4Arizona State University 5AWS Agentic AI
*Equal contribution †Project lead
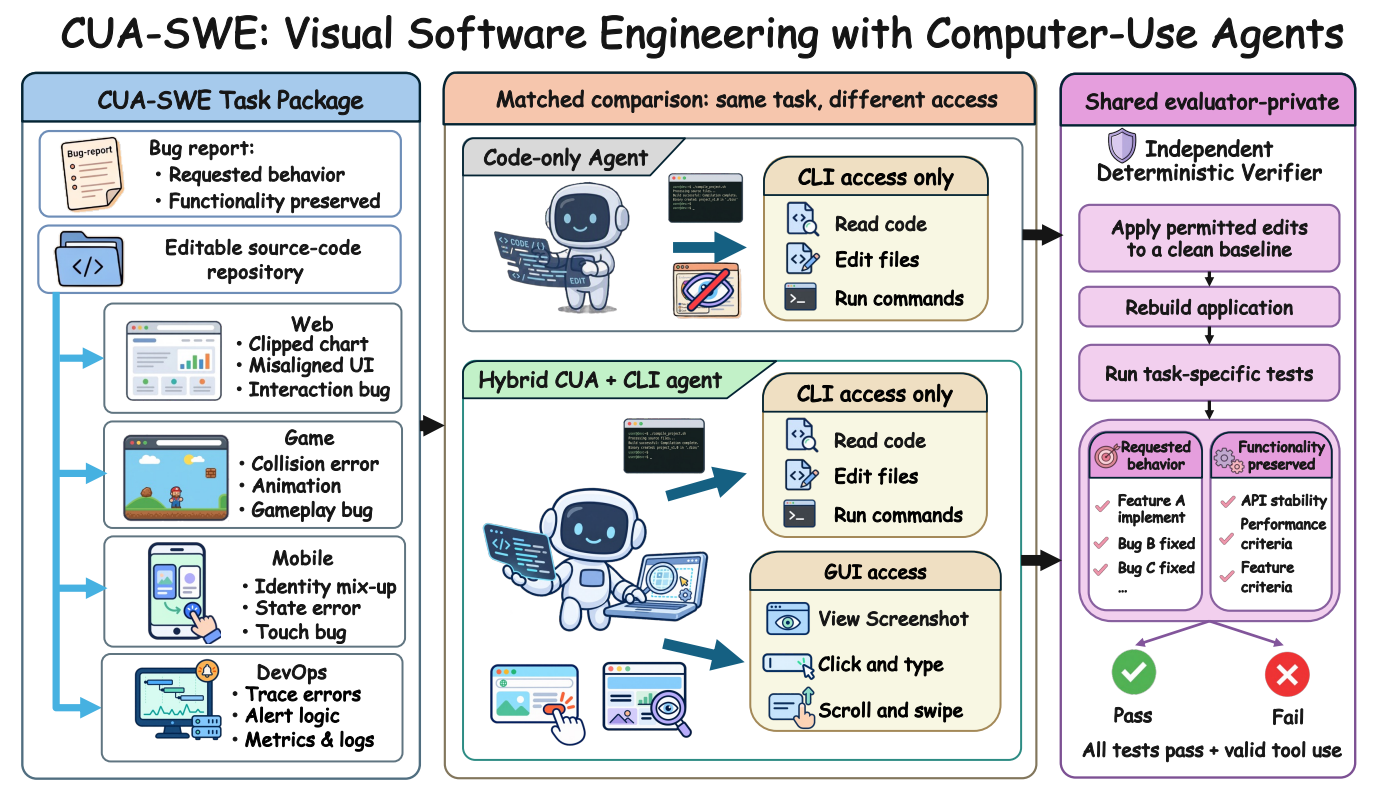
CUA-SWE provides a benchmark and environment where coding agents need to repair the software by using it and visually inspecting it. Each of the 105 tasks (36 Web, 29 Game, 20 DevOps, 20 Mobile) gives the agent an editable project and the running application; deterministic, task-specific tests then judge the repaired software on a clean copy of the project. Adding computer use to coding raises task success for all eight models evaluated with and without it in every domain.
Web
Browser apps on real libraries. Layout and interaction bugs.
 MapLibre
 ECharts
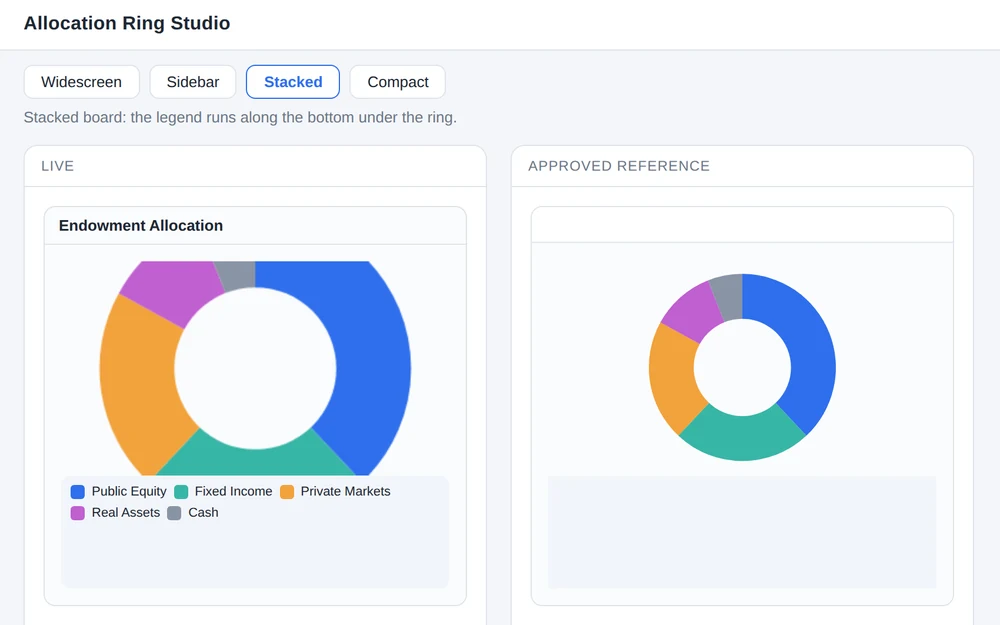
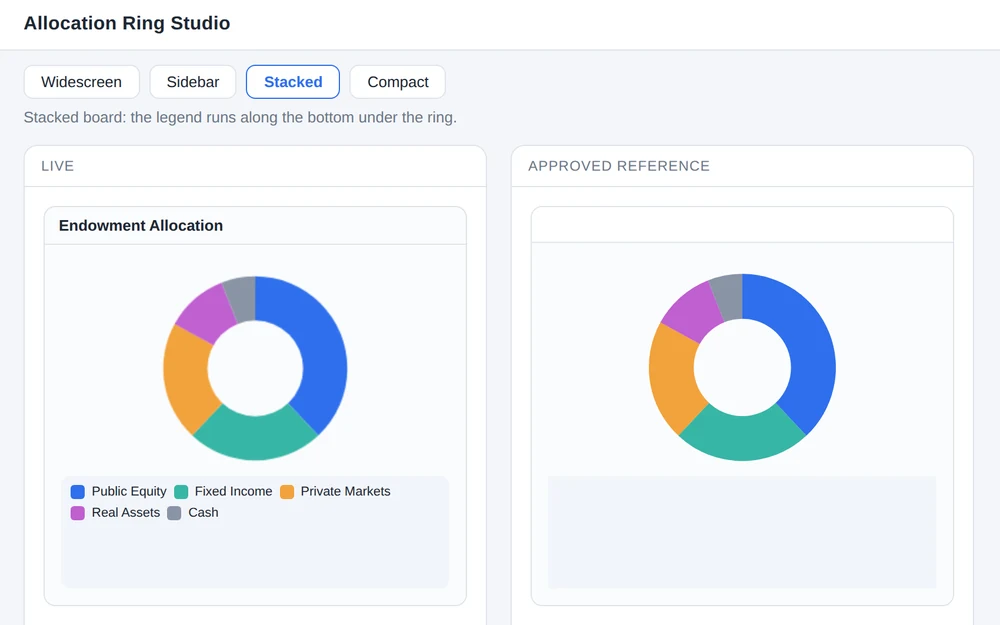
Allocation Ring Studio. The ring chart overflows its card in the Stacked layout.The ring fits its card in every layout.
Game
Open-source browser games. Timing, physics and state bugs that show only in play.
 Captain Callisto
 Hextris2048
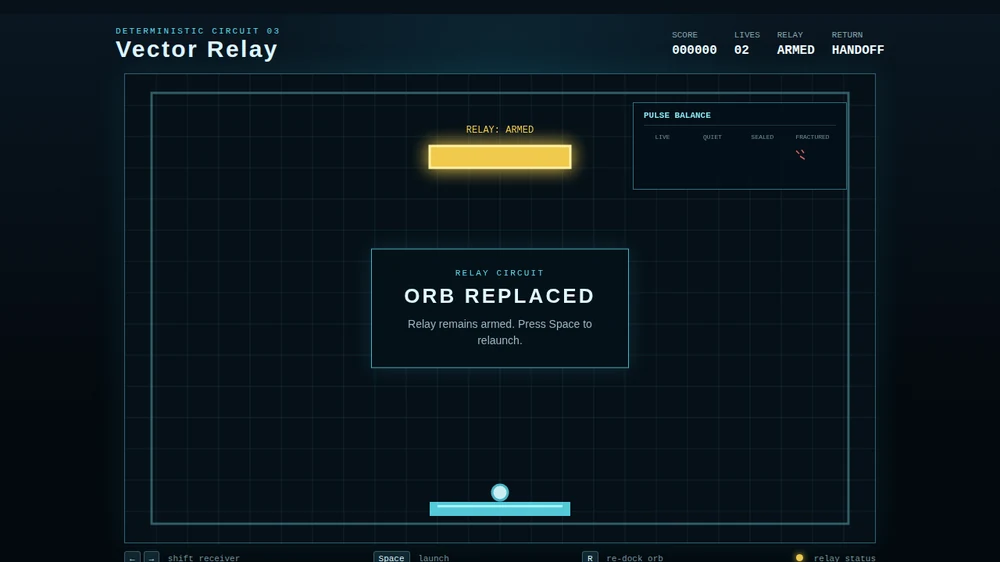
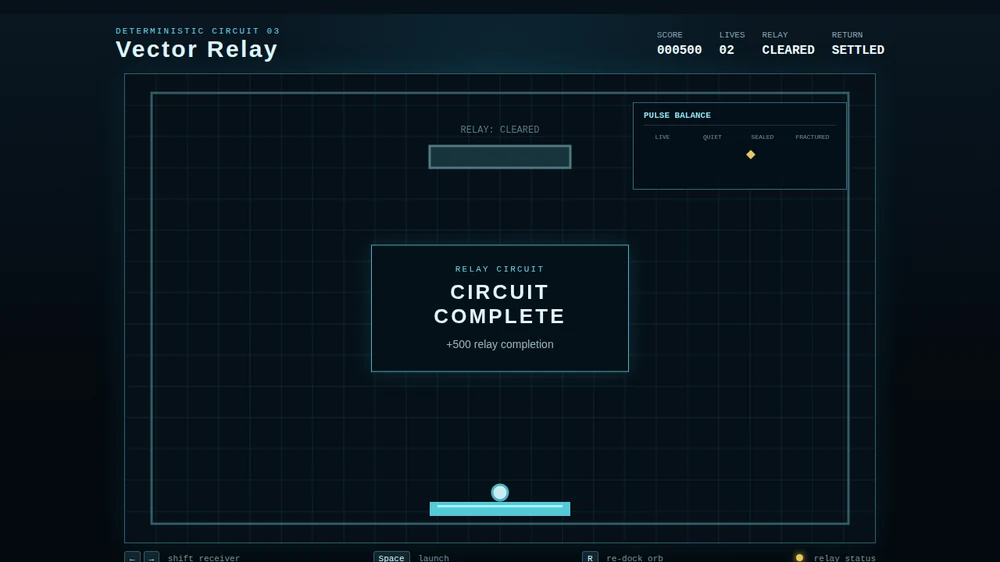
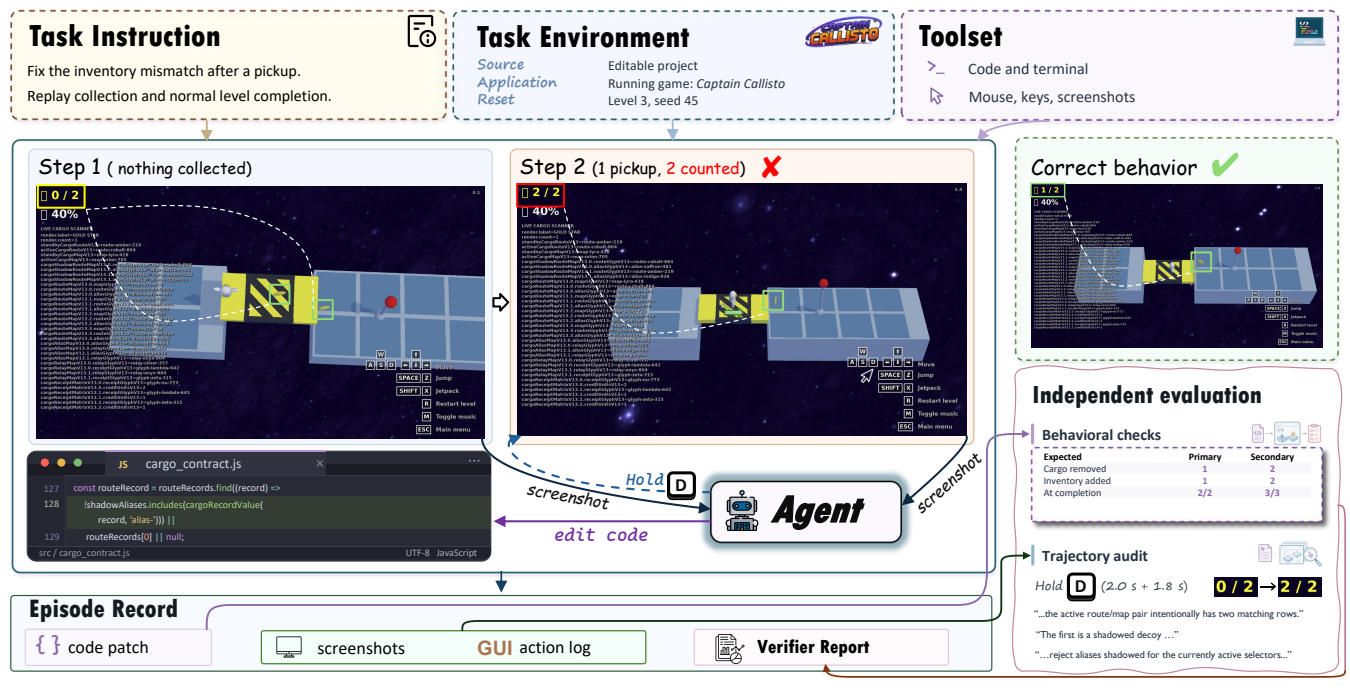
Captain Callisto. Picking up one item counts as two: the cargo counter jumps to 2/2.One item counts once: the cargo counter reads 1/2.
DevOps
Consoles for traces, alerts, logs and metrics. Fix the config or pipeline behind them.
 Prometheus
 OpenTelemetry
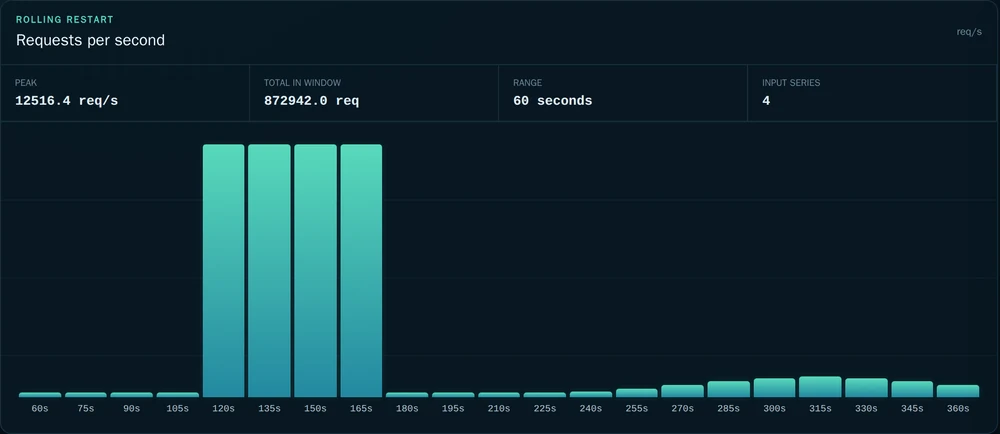
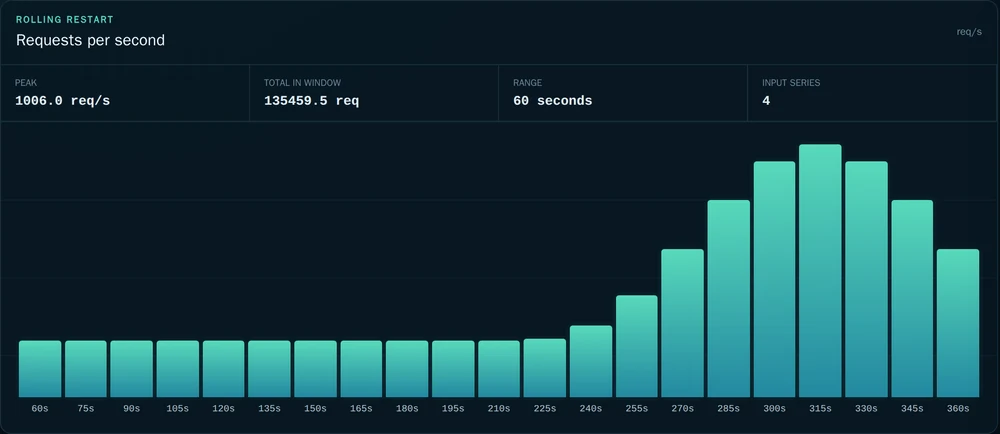
Counter Order Console. A rolling restart shows up as a 12,516 req/s traffic spike.The false spike is gone; the real burst later on remains.
Mobile
Phone apps that import drawings and plans. Make the app agree with them.
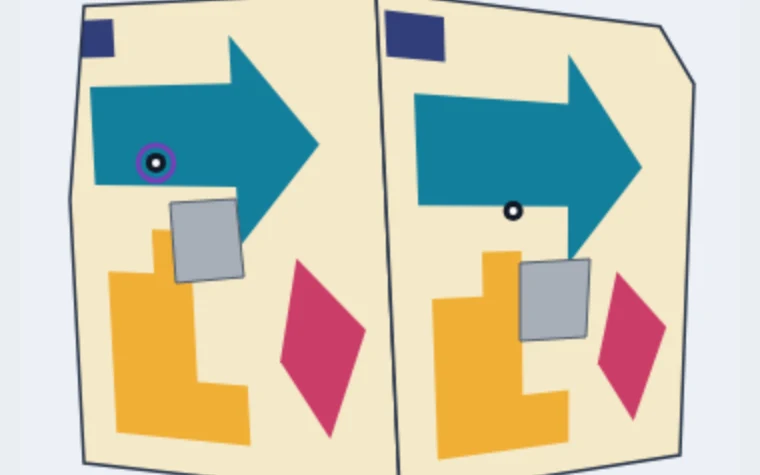
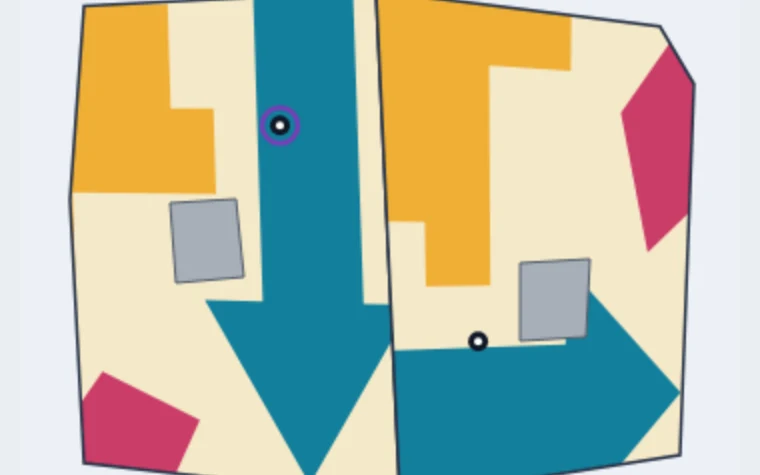
Mural Desk. The artwork is projected onto the wall plan the wrong way.The artwork lines up with the wall plan.
Results
Task success (%) on a single attempt per task, model and condition. Code-only uses the coding interface: read and edit source, run commands. Hybrid adds computer use: screenshots of the running application and mouse and keyboard actions. Both conditions share the same tasks, budgets and hidden tests, so the gap isolates what visual feedback and interaction contribute.
Lighter bar: Code-only Solid bar: Hybrid (computer use + coding) +pp Red label: Hybrid gain in percentage points One hue per model: GPT, Claude, Grok, agent systems
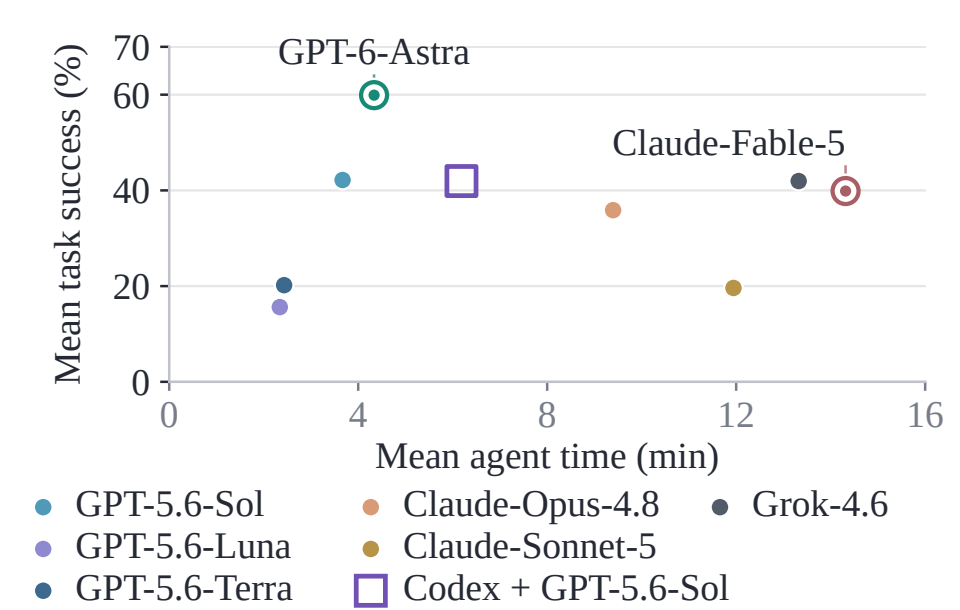
Panel a weights the four domains equally and matches the right panel of Figure 1 in the paper; Opus 5 is omitted because its Mobile evaluation is deferred. Panel c is Figure 6a of the paper (circles: frontier models; open square: Codex). Codex and Claude Code are evaluated as complete agent systems in the Hybrid condition only. Each domain retains its original scoring rules: Web success also requires the required visual evidence; DevOps and Mobile exclude infrastructure errors and count genuine agent failures. Table 4 in the paper reports a three-attempt Hybrid evaluation of GPT-6 Astra, GPT-5.6 Sol and Fable 5.
Table 1 in the paper: single-attempt task success (%) for every model, domain and condition
Column maxima are in bold. Hover a cell for the number of solved tasks.
Examples
Three recorded runs, one per tab. Fabric.js is GPT-6 Astra’s scored Web attempt and Minesweeper a GPT-5.6 Sol run, both replayed as they happened; Vector Relay follows GPT-5.6 Sol step by step, with its edits and the verifier’s result.
Tasks
Every task starts from a verified bug in a working application and specifies the failure to fix, the behavior to implement and the existing functionality to preserve. Related variants share application code and test different interactions or configurations.
Web 36 tasks, 20 applications
Bugs in visual layout, geometry and interaction state. The applications use Fabric.js (9 tasks), MapLibre (7), React Spectrum, JupyterLab, Quill, ECharts and other open-source libraries, or implement business workflows such as account recovery, tax rounding and warehouse cutoffs.
Example instructionMake the account recovery page display the channel selected by the live identity risk policy for the account being viewed, including ACC-731, while preserving the recovery decision trace.
Game 29 tasks, 12 games
Bugs in motion, timing and state transitions in browser games, among them 2048, Flappy Bird, Minesweeper, Hextris and Captain Callisto. Tests set initial states, apply inputs and restart with fixed seeds.
Example instructionThe deterministic Level 3 benchmark build contains a gameplay regression. Play the pulse lane and compare the start, release, and restart of several short jetpack bursts.
DevOps 20 tasks, 10 fault types
Service consoles in which a displayed observation traces back to configuration or processing logic: rate before aggregation, alert inhibition, log severity, SLO rollups, tail sampling and trace clock skew, on Prometheus, Alertmanager, Jaeger and OpenTelemetry code.
Example instructionAfter the collector rollout, failed operations are missing from the log workbench’s severe view while a routine event appears as an error. Investigate the live records and receiver fleet, then repair severity classification.
Mobile 20 tasks, 12 applications
Mobile-web applications, run in Chromium at 400×800, whose displayed behavior is tied to application state and specified in part by imported drawings or documents: nine Gantt wall-chart variants and eleven other applications such as Mural Desk, Foldnote, Pass wallet and Campus Pocket.
Example instructionFoldnote is a mobile web packaging-proof review mockup. Review markers no longer stay correctly placed and oriented when switching between Flat sheet and Individual panel.
Where the requirements are specified
Tasks differ in where their requirements are specified; the paper calls this the specification basis. In source-specified tasks (42), the instruction and readable project code define the target behavior; running the application supports diagnosis and checking. In application-material-dependent tasks (63, material-dependent for short), part of the behavior is specified only through application materials such as an imported drawing, a displayed service contract or a graphical reference card, which the code-only interface does not expose. Both groups require implementing the behavior and verifying the resulting software.
Two example tasks
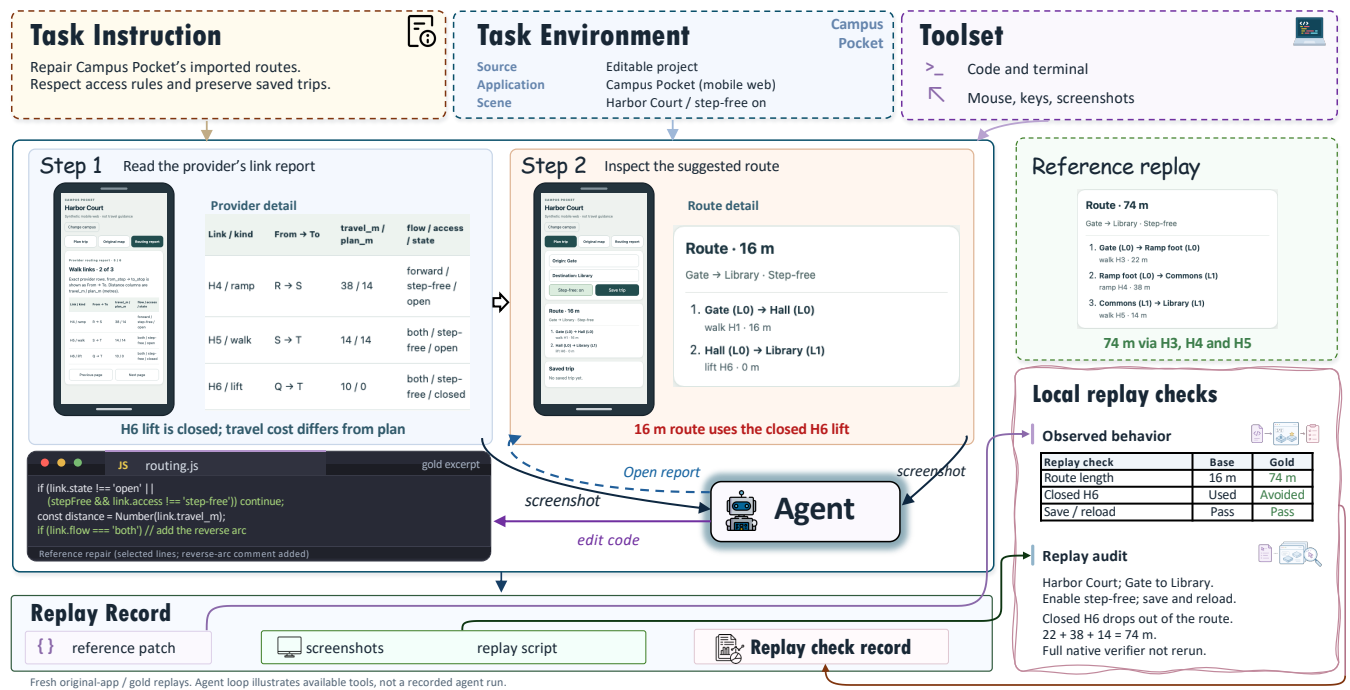
Browse all 105 tasks with their original instructions, budgets and tests
Analysis
Where the gains come from
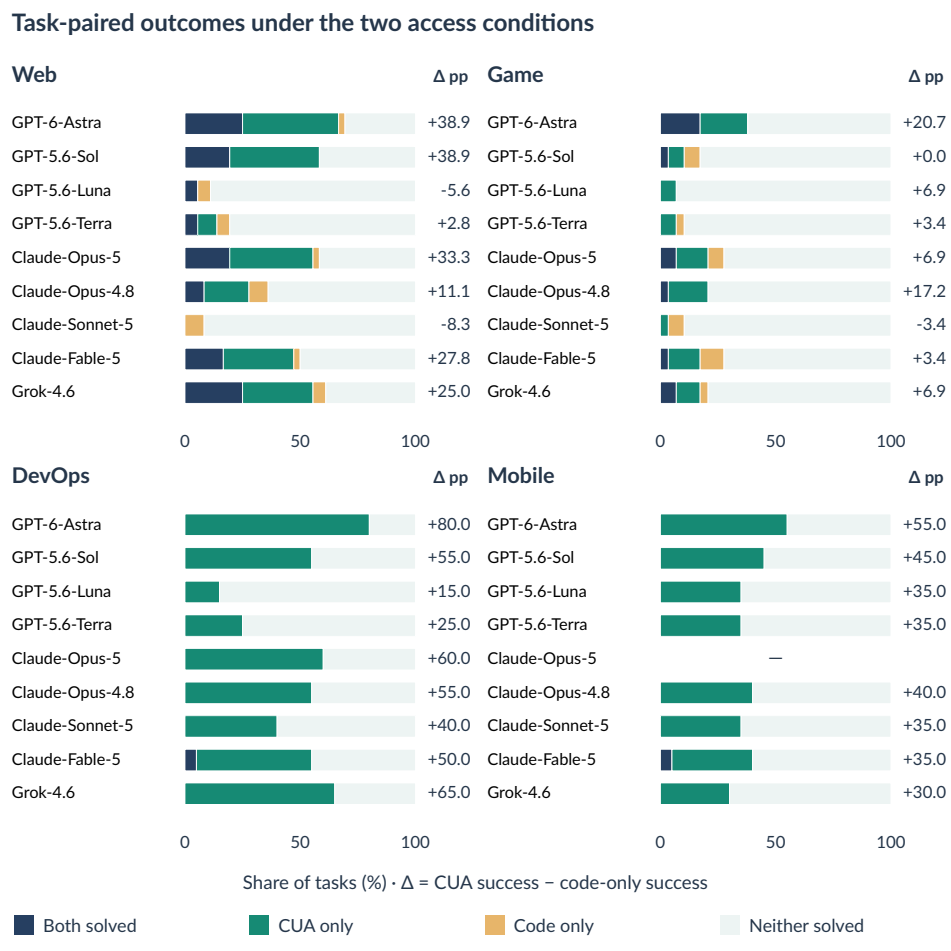
The gains concentrate on material-dependent tasks, while source-specified subsets have near-zero domain-average changes and substantial variation across models.
| Domain | Requirements | Tasks | Code-only | Hybrid | Δ pp |
|---|---|---|---|---|---|
| Web | Source-specified | 22 | 23.9 | 23.9 | +0.0 |
| Web | Material-dependent | 14 | 8.9 | 50.9 | +42.0 |
| Game | Source-specified | 20 | 10.6 | 10.0 | −0.6 |
| Game | Material-dependent | 9 | 2.8 | 26.4 | +23.6 |
| DevOps | Material-dependent | 20 | 0.6 | 48.8 | +48.1 |
| Mobile | Material-dependent | 20 | 0.6 | 39.4 | +38.8 |
In material-dependent tasks the agent must recover requirements from drawings or displayed behavior, implement them and preserve the surrounding workflow. Source-level execution tests the implementation; application observations supply requirements and feedback that those executions alone may not expose. The same figure also shows the limits: a few Web tasks are solved only with code, and most Game tasks remain unsolved under both conditions.
How agents turn runtime observations into correct changes
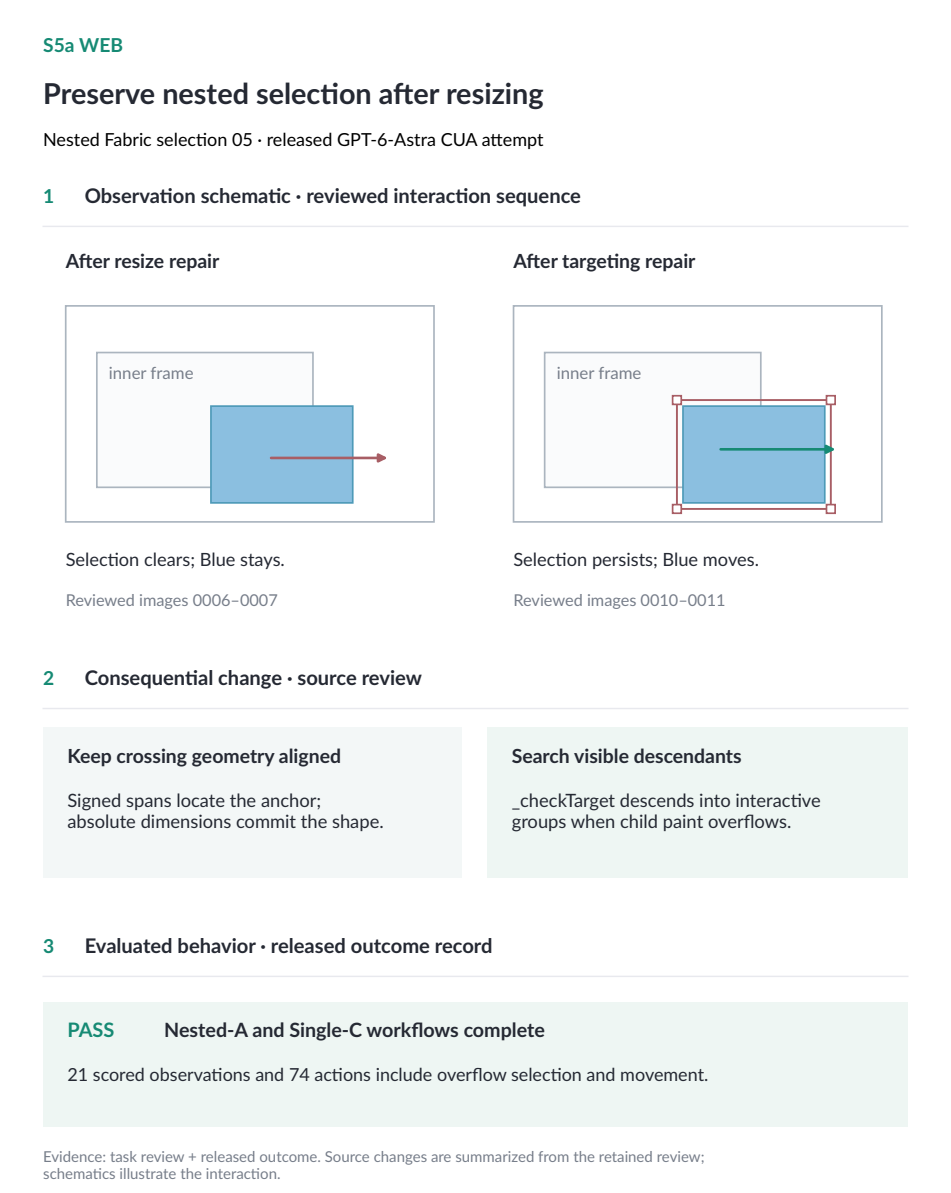
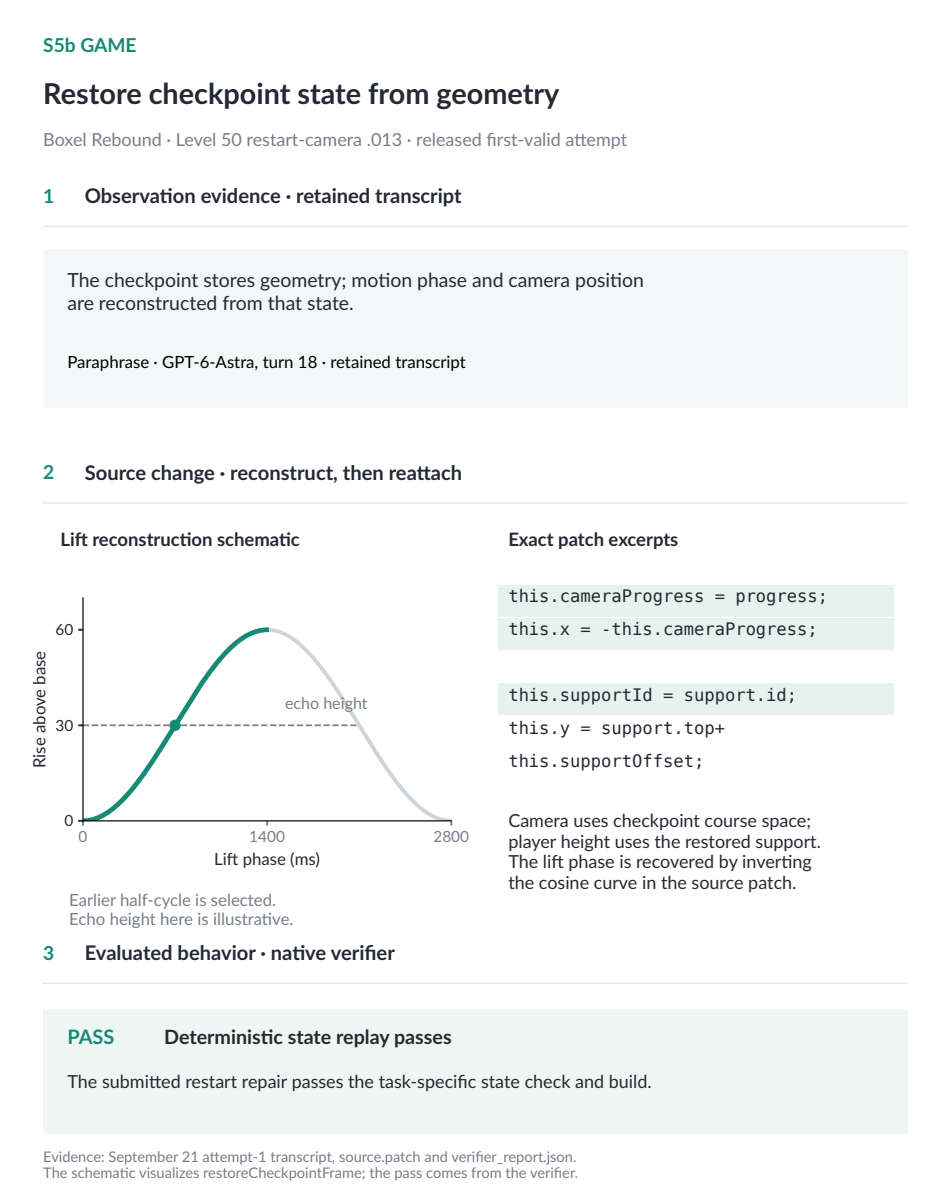
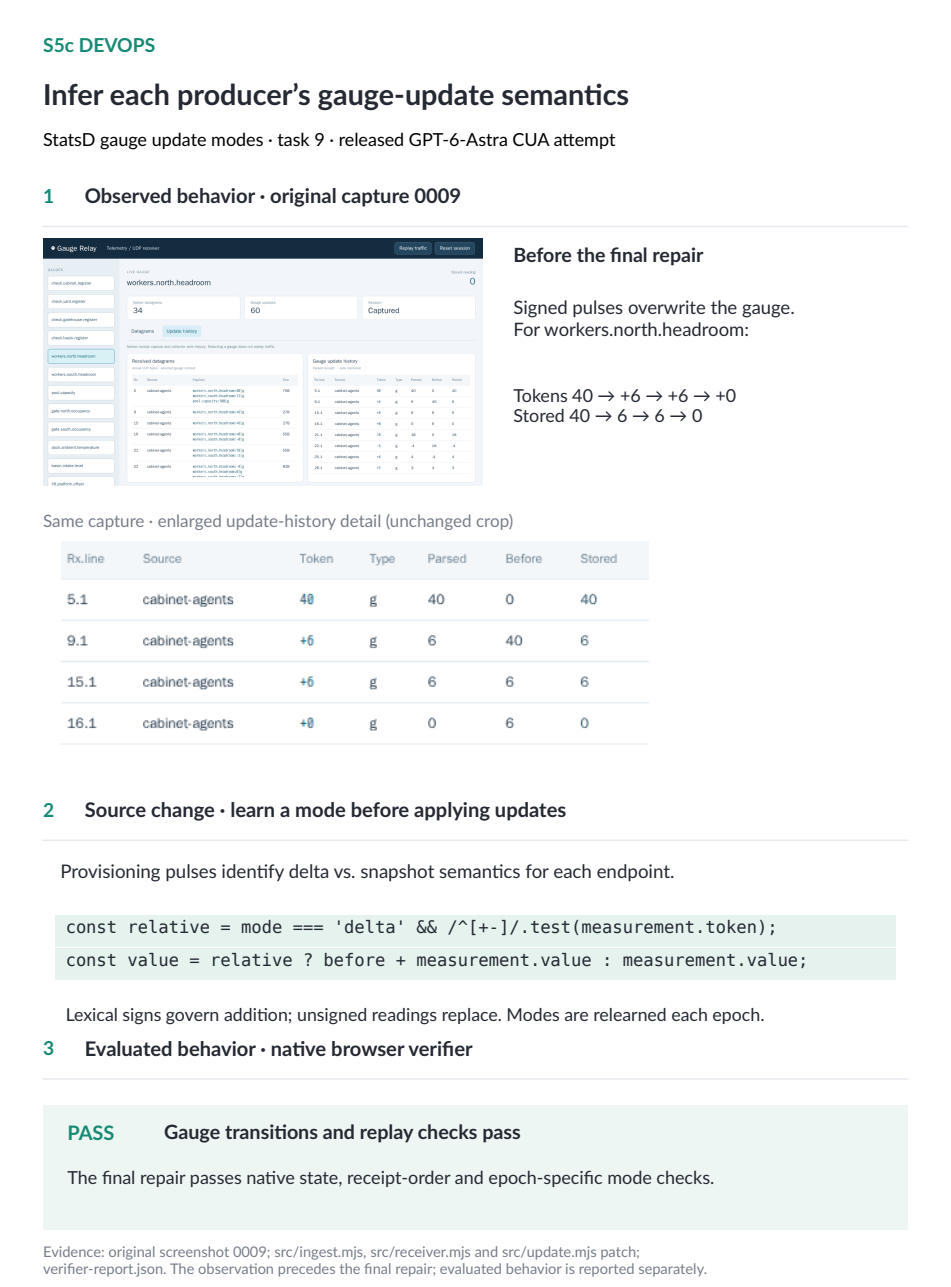
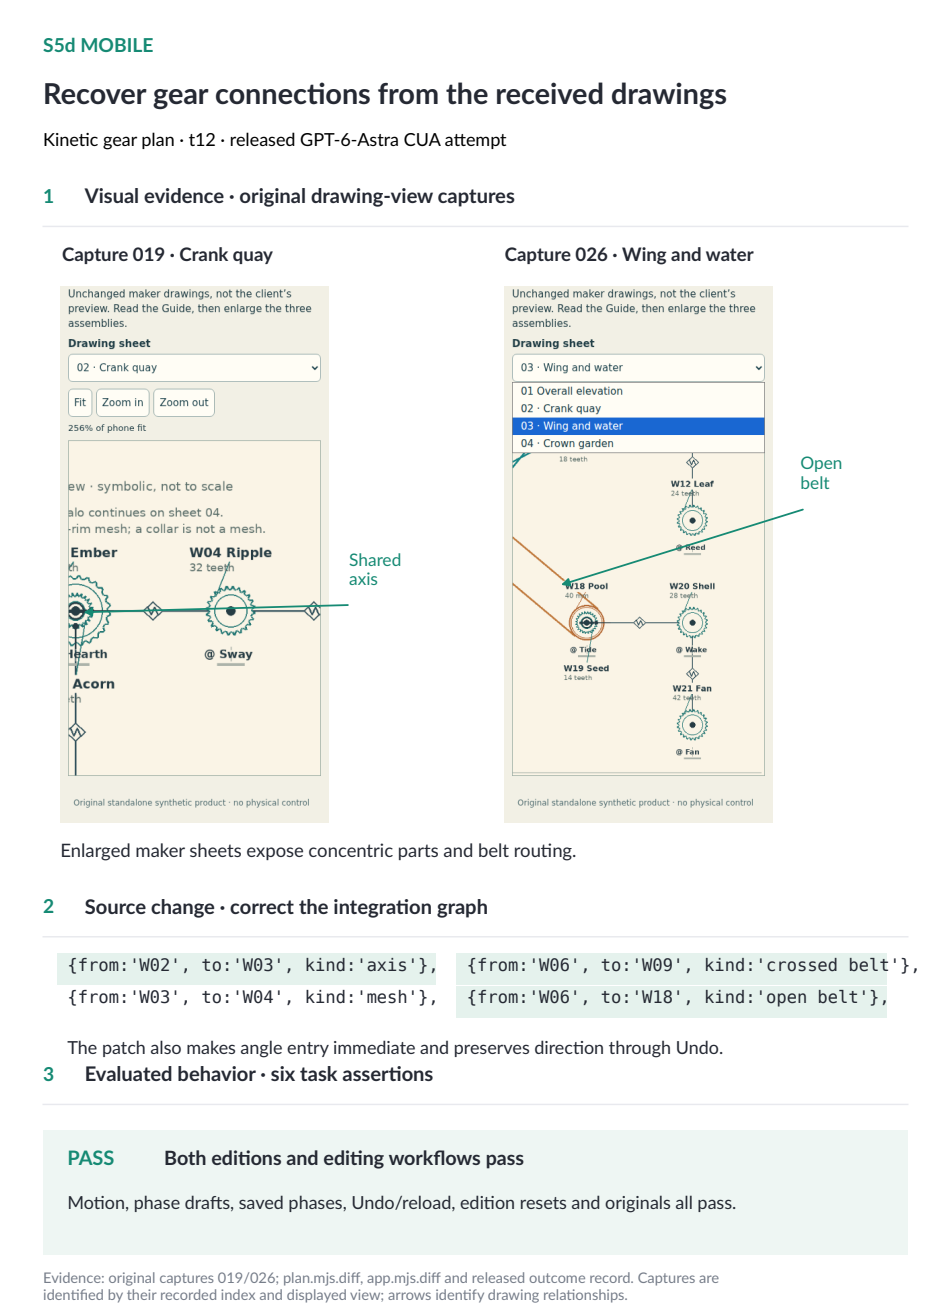
Four released GPT-6 Astra attempts, one per domain, as reviewed in the paper (Figures 28 to 31). Each figure shows what the agent observed, the source change that followed and the evaluator's verdict. Click a figure to enlarge it.
Where repairs still fail
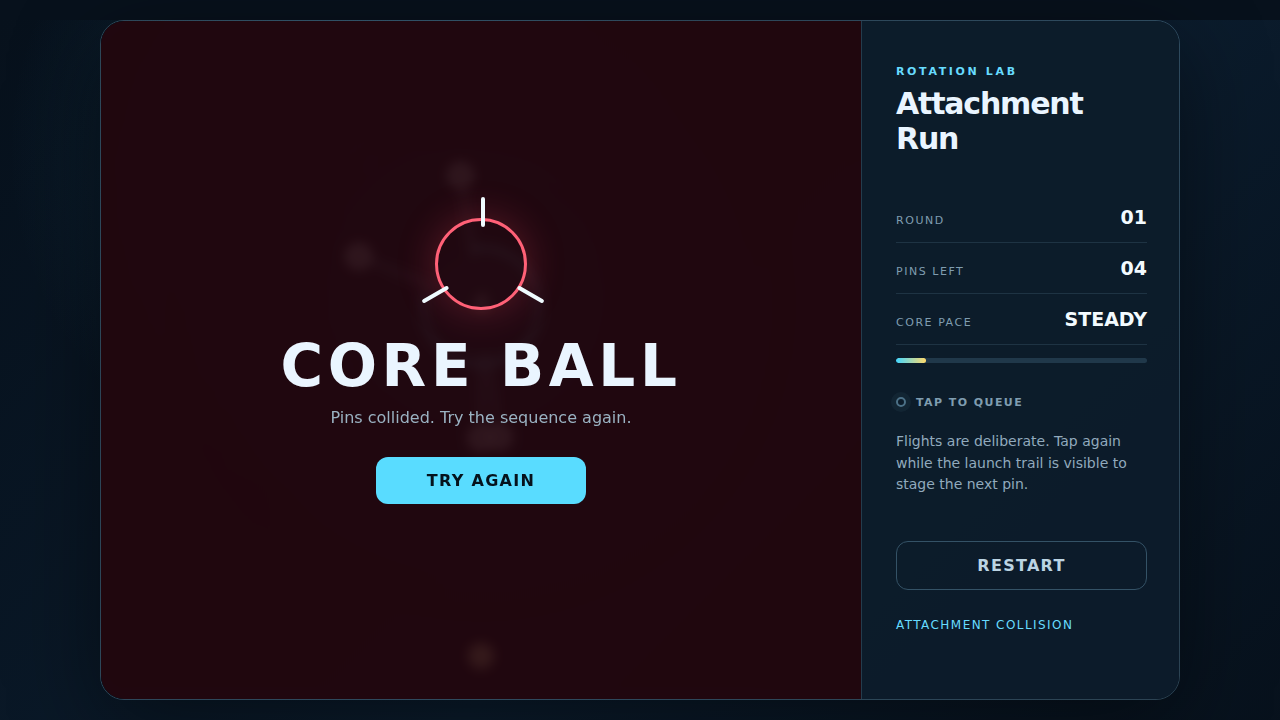
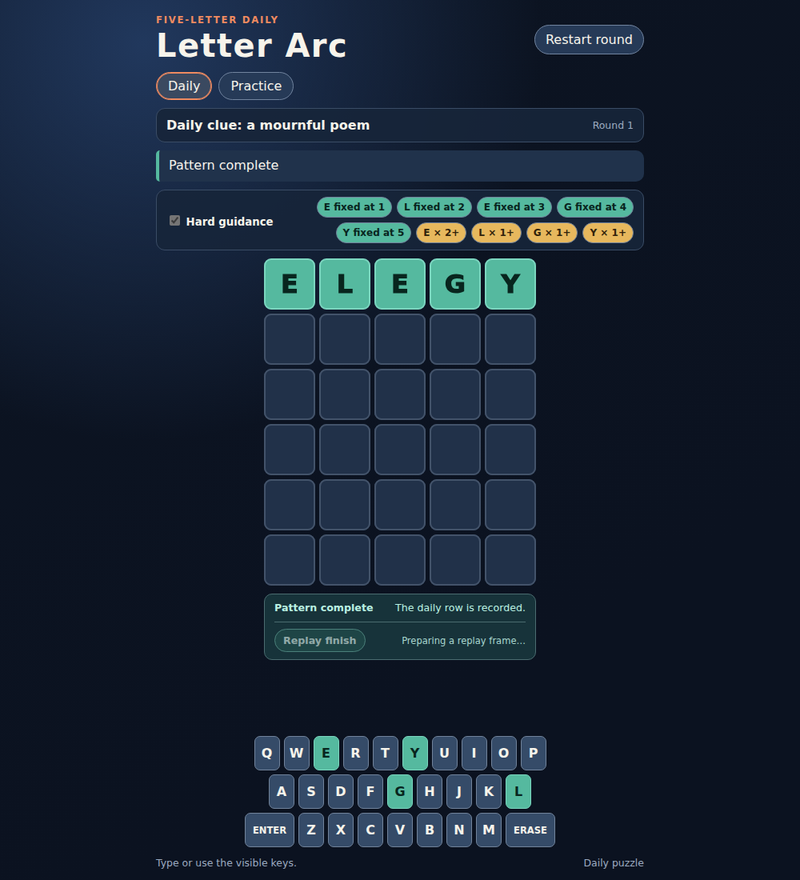
Evaluation
What counts as a success
| Check | Question | How it is decided |
|---|---|---|
| Task check | Does the requested behavior work? | Tests execute the rebuilt application under controlled interaction sequences and assert on the rendered interface, runtime behavior or internal application state. |
| Regression check | Does designated existing behavior still work? | The same tests cover the functionality the task says must be preserved, so a fix that breaks normal play, editing or navigation fails. |
| Permitted-change check | Did the patch stay inside the allowed scope? | Edits outside the files the task permits fail regardless of test results. |
These three checks give patch correctness. Reported task success additionally requires a valid trajectory: the run used only the interfaces allowed by its condition and, for Hybrid runs, actually observed the screenshots. Correctness depends on the behavior of the submitted program, not on matching the reference patch; the evaluator may inspect privileged state such as a game board that the agent only sees rendered.
How tasks are built and validated
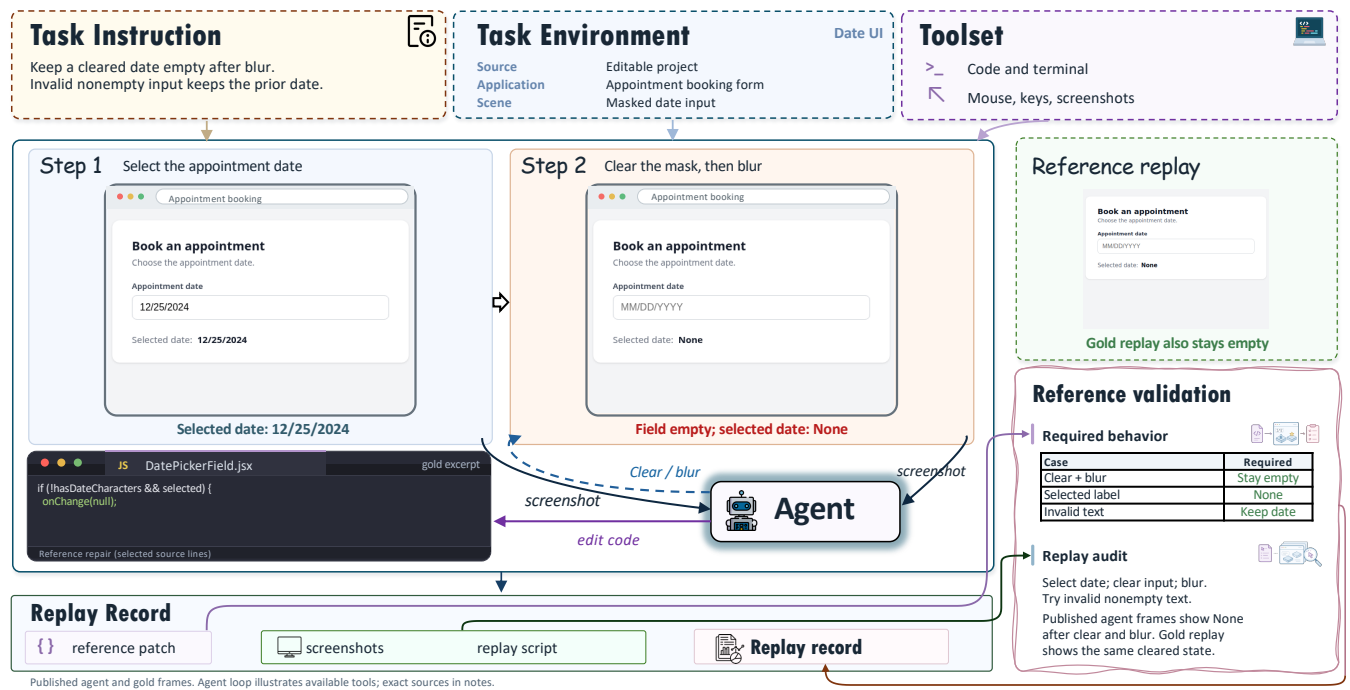
Each task starts from a software behavior that can be reproduced in the running application and modified in the codebase. An LLM author constructs the instruction, initial codebase, runtime setup, gold reference repair, plausible negative repairs and protected tests; human review checks that the requirement is meaningful and that the relevant runtime evidence is observable through the benchmark interface. The verifier must reject the broken project and every negative repair and accept the gold repair; the figure below shows this for one task. Reviewed construction-time agent trials then guide neighboring variants that extend each task family's difficulty range.
Citation
@misc{wang2026cuaswe,
  title         = {CUA-SWE: When Computer-Use Agents Meet Visual Software Engineering},
  author        = {Wang, Prince Zizhuang and Liang, Chenhao and Xu, Zelong and Yuan, Aojie and Zhou, Xiaolin and Zhang, Haiyue and Zhao, Yue and Hu, Xiyang and Jiang, Shuli},
  year          = {2026},
  eprint        = {2609.32600},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2609.32600}
}